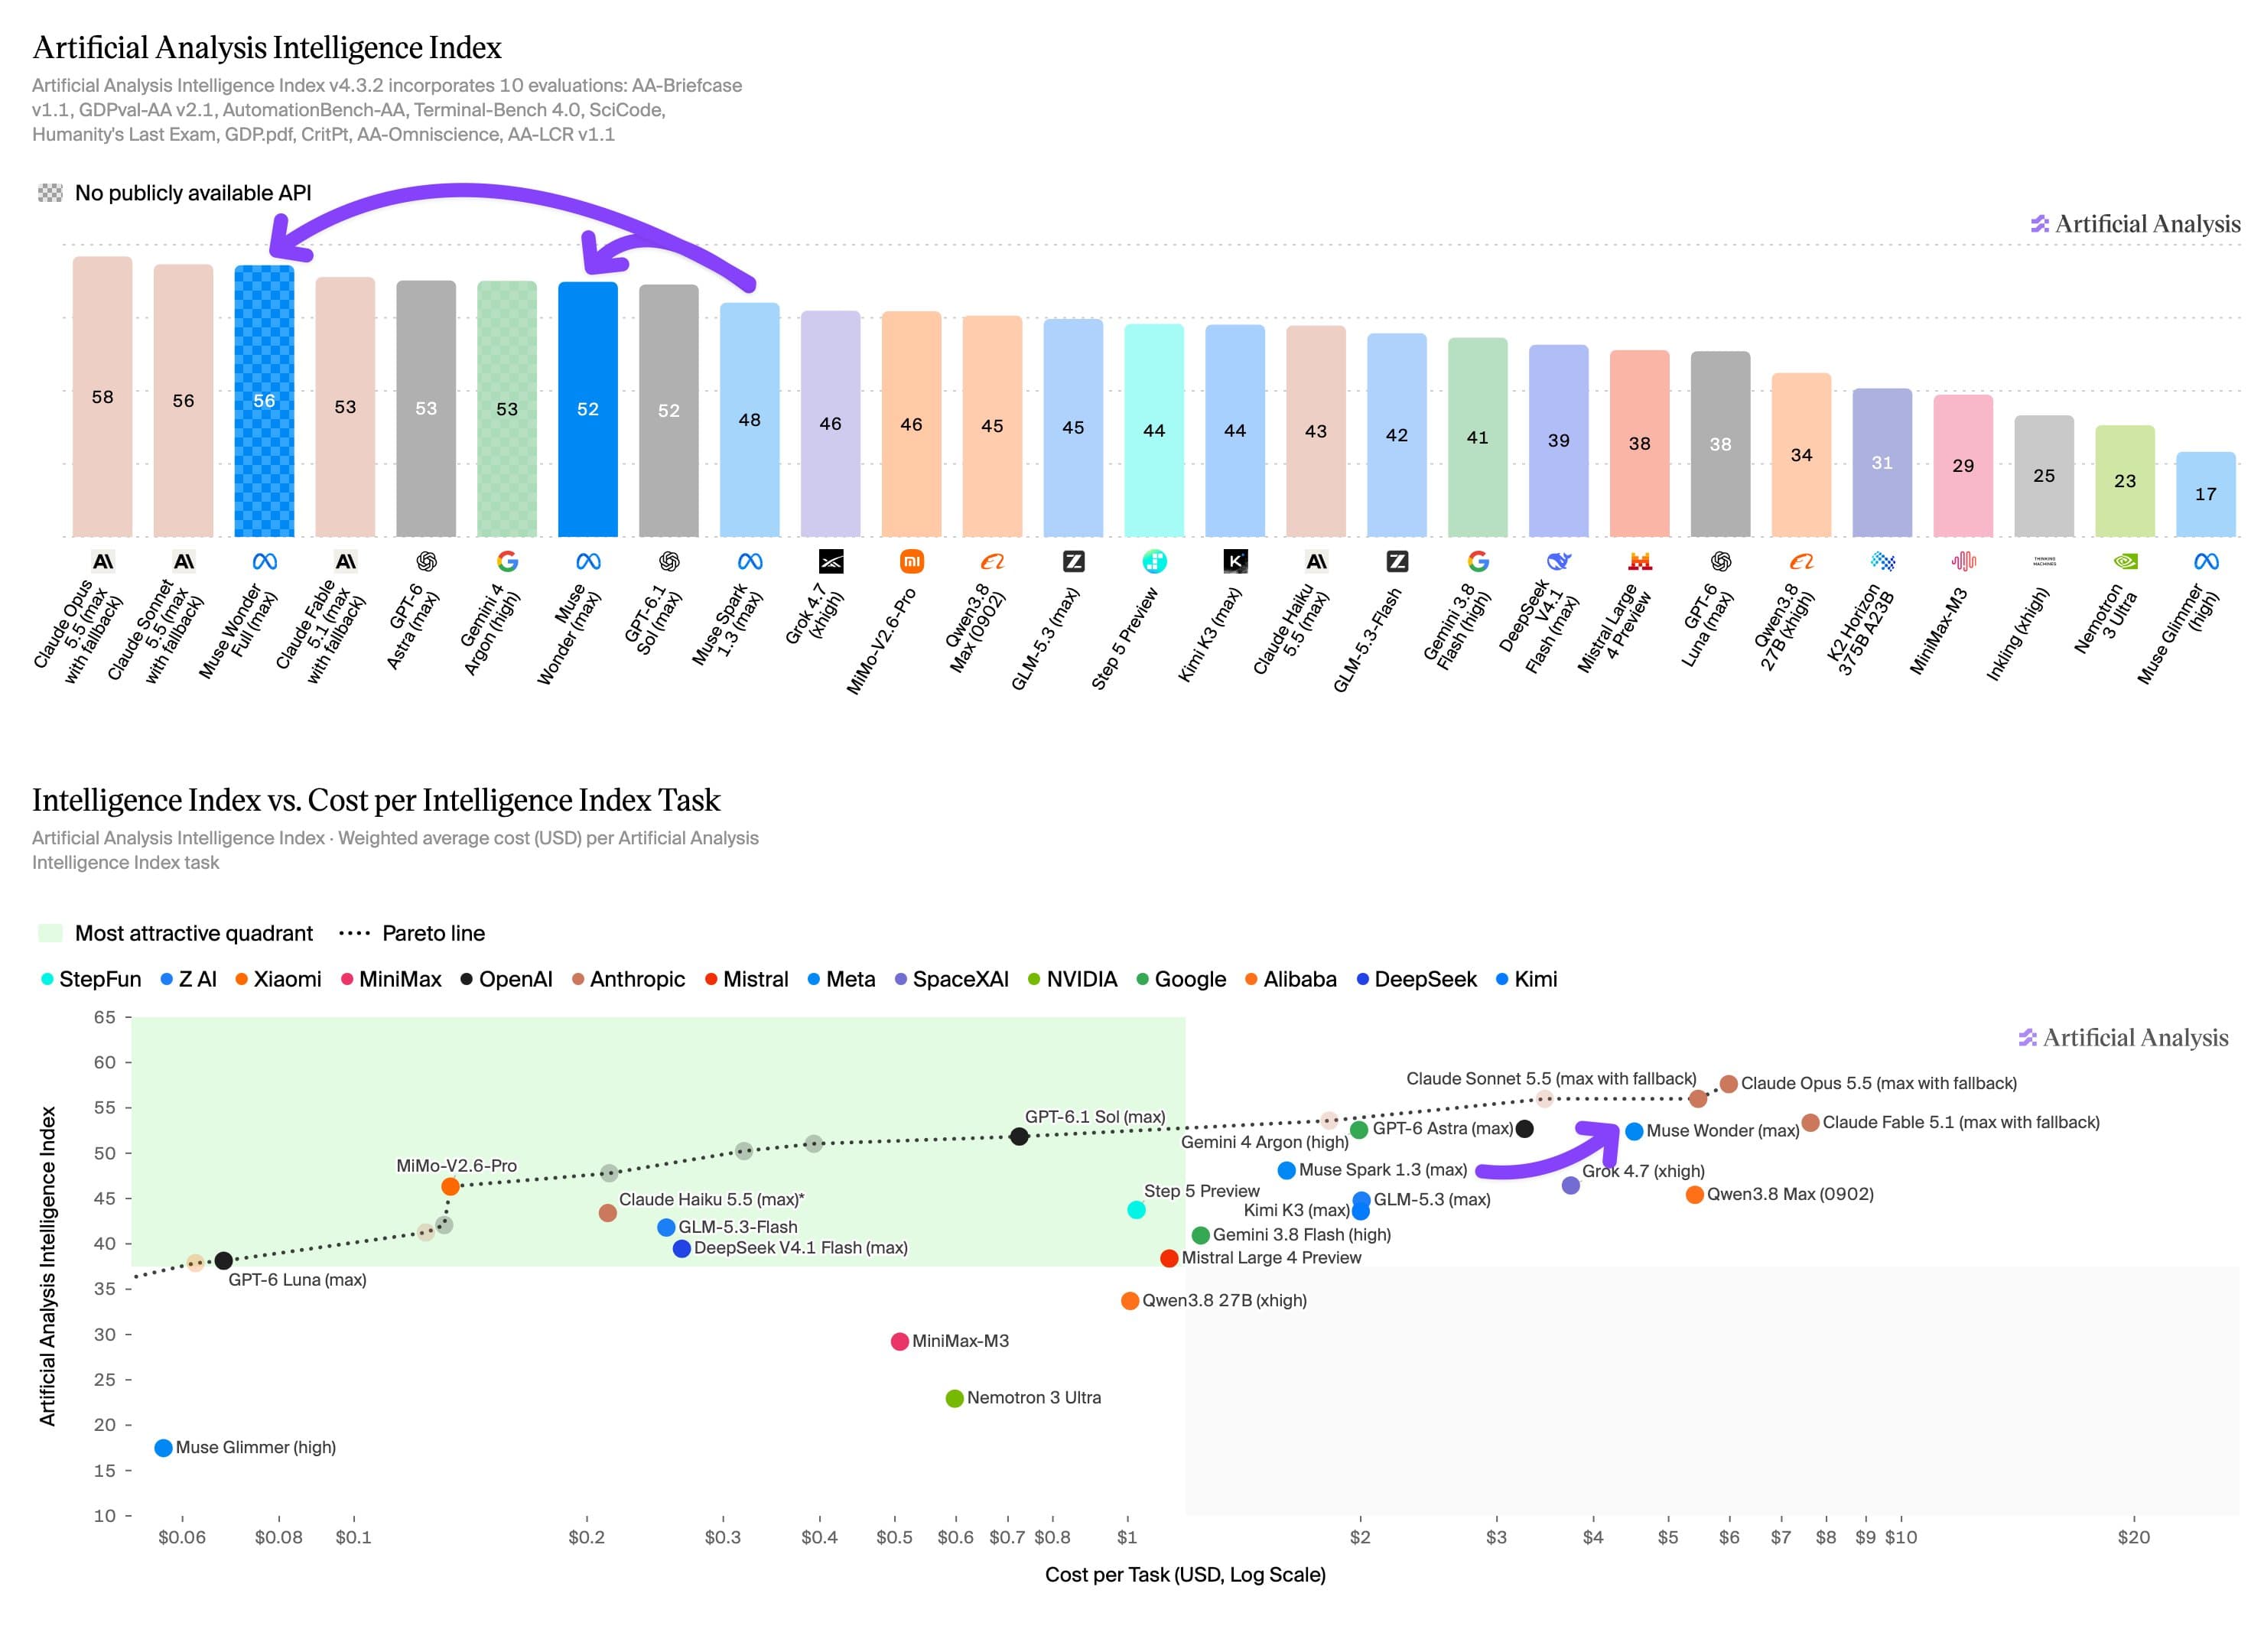
«Meta released Muse Wonder and Muse Wonder Full: at maximum reasoning they scored 52 and 56 points on the Artificial Analysis Intelligence I…» — Artificial Analysis
«Meta released Muse Wonder and Muse Wonder Full: at maximum reasoning they scored 52 and 56 points on the Artificial Analysis Intelligence I…» — Artificial Analysis
«The Cursor team is genuinely very talented.
What I don't get: now that they're at SpaceX, why would anyone with offers from Anthropic, OpenAI or GDM go to SpaceX, given how badly Musk's companies treat engineers.
It's hard to imagine top people going there unless they're hired through an acquisition for big money.»
«We deliberately bypassed QuickJS in our codemode implementation.
It brings WebAssembly complexity, forces us to spin up worker threads, and shuttles values back and forth through serialization.
If you're building something similar yourself, check out our codemode package: it's much simpler.»
«We deliberately bypassed QuickJS in our codemode implementation.
It brings WebAssembly complexity, forces us to spin up worker threads, and shuttles values back and forth through serialization.
If you're building something similar yourself, check out our codemode package: it's much simpler.»
«Verification is one of the most important things for getting excellent results from an agent.
Define clearly what “done” means before code review starts. A reviewer, human or agent, asked to find bugs without that will still find something to improve.
Give Claude checks it can run (bash commands, tests, clicking through the app in a browser), and have it run them too before it says it's finished. When nothing blocks merging and shipping, then it's done.»
«Continuous fuzzing finds real bugs, but you still need a person who writes the harnesses, watches coverage and goes through every crash.
GitHub Security Lab built Fuzzing Taskflow to hand this loop to an agent. Point it at a C or C++ repository. It will find entry points, work out the build, write harnesses, run the AFL++ fuzzer, read the coverage, and create a vulnerability report for each unique bug.
See how the pipeline works from start to finish 🔍
https://github.blog/security/application-security/ai-powered-fuzzing-with-the-github-security-lab-taskflow-agent/»
«This is literally my new workflow:
Real-time research and planning → Grok Bot
Work assistant → Grok Bot
Architecture → Opus 5.5
Day-to-day code and debugging → Sonnet 5.5
Writing and running tests → Sonnet 5.5
Complex code → Opus 5.5
Frontend and design → Opus 5.5
Bookmark it.»
«This is literally my new workflow:
Real-time research and planning → Grok Bot
Work assistant → Grok Bot
Architecture → Opus 5.5
Day-to-day code and debugging → Sonnet 5.5
Writing and running tests → Sonnet 5.5
Complex code → Opus 5.5
Frontend and design → Opus 5.5
Bookmark it.»
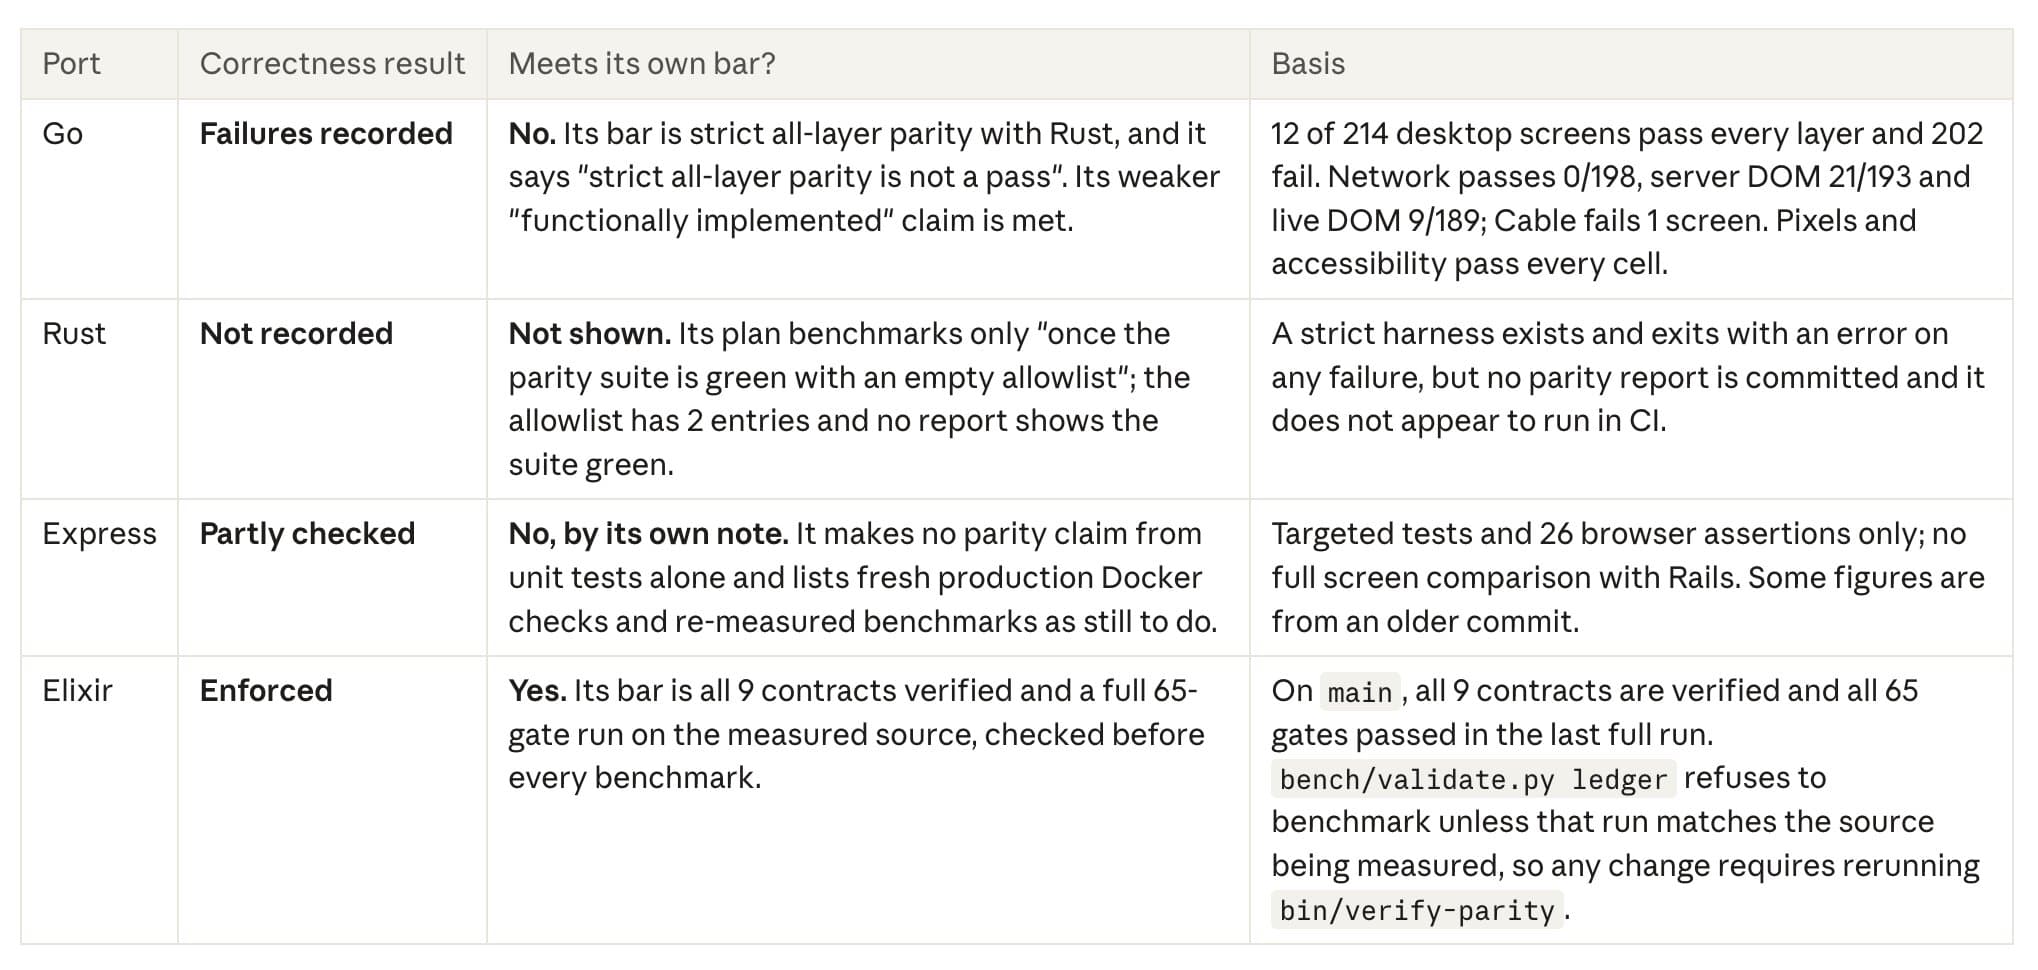
«I was trying to figure out why AI agents reject PRs that speed up the Elixir version, while accepting PRs in Go, Express and Rust.
It turn…» — José Valim
«I was trying to figure out why AI agents reject PRs that speed up the Elixir version, while accepting PRs in Go, Express and Rust.
It turn…» — José Valim
«A playbook is taking shape for product managers at large companies who try zero-to-one ideas:
row, then steer.
1. Row: a PM and a designer…» — Lenny Rachitsky
«A playbook is taking shape for product managers at large companies who try zero-to-one ideas:
row, then steer.
1. Row: a PM and a designer…» — Lenny Rachitsky
«We're starting to publish reports on model behavior more often than what goes into system cards and regular risk reports.
Today's report describes four types of behavior we found during evaluations and internal use. In each, Claude acted on real websites or in systems in ways we didn't intend, sometimes working around a restriction instead of stopping.
All of the cases had minimal impact in the real world. From an alignment and safety standpoint, we consider these behaviors significantly less serious than the cyber incidents we reported in July and September.
Read the full report: https://www.anthropic.com/research/investigating-unintended-model-actions»
«Your edge right now is understanding what’s possible and staying curious.
Using AI in development is now the default. Engineers who have an edge are ambitious and have worked with agents on the job for years. It’s the compound interest effect.
For teams that are still hesitating or falling behind, I’d offer the most sensible advice: be more ambitious and actively share your findings with colleagues. If you do all this work alone, only you benefit. If a team only tries AI after work, you’ve quietly signaled that it doesn’t count.
Senior engineers should take this step first. A decade of taste for system design and knowing how things break is what makes agent output good. Let them point their experience at making agent work safer. Then let them show the rest what works so others can repeat it.»
«A reminder: Claude Max and Team now include monthly API credits.
Max 5x: $100, Max 20x: $200
Great for building apps and agents with the API, Managed Agents or Agent SDK. We hope you'll enjoy Opus 5.5 there too.»
«A reminder: Claude Max and Team now include monthly API credits.
Max 5x: $100, Max 20x: $200
Great for building apps and agents with the API, Managed Agents or Agent SDK. We hope you'll enjoy Opus 5.5 there too.»
 From a tweet@artificialanlys10/12
 From a tweet@artificialanlys10/12